A health percentage cannot answer three different questions
An SSD report might show substantial wear while files still open normally. Another drive might have little estimated wear and nevertheless refuse writes. Before ordering a replacement, separate three questions: how much endurance has been consumed, whether the controller reports a current problem, and whether your files are safely recoverable.
This article explains those distinctions for an ordinary NVMe SSD. It includes a Linux report-capture route using smartmontools; the interpretation also helps when another utility exposes the same named NVMe fields. SATA SSD attributes need their own model-specific interpretation. No report here establishes a failure date, and none of the examples represents a tested drive.
If files are disappearing, reads stall repeatedly, or the drive keeps disconnecting, protect the data before collecting more evidence. Copy irreplaceable files to separate storage if reads remain stable, then open the destination copies. If the only copy is valuable and reads are deteriorating, stop experiments and consider a recovery specialist. A replacement can restore a working computer without recovering its missing files.
First establish whose report you are reading
On Linux, use an installed smartmontools package from your distribution, or ask an administrator to collect the report. In a terminal, run:
sudo smartctl --scan-openThe official smartctl manual documents this discovery option and -x for comprehensive device information. Use the detected path and any reported -d device-type option. For a directly attached NVMe controller discovered as /dev/nvme0, run:
sudo smartctl -x /dev/nvme0That path is an example, not an instruction to assume the first controller is yours. Match the model, serial number and capacity against the intended SSD before interpreting anything. Save the complete output, including warnings, with the capture time and utility version; keep the saved copy somewhere other than a suspect drive.
Capture succeeds when the identity matches and the report contains the health fields you intend to evaluate. Permission denied, an unsupported bridge, or missing health data means the capture is incomplete, not that the SSD passed. USB bridges and RAID arrangements can complicate access; do not guess device-type switches to force a result.
Before sharing the report publicly, redact the serial number from a duplicate. Preserve the unedited original for support. If comparing two reports, confirm they belong to the same physical drive rather than merely the same device path.
Read the direction of the percentage before judging it
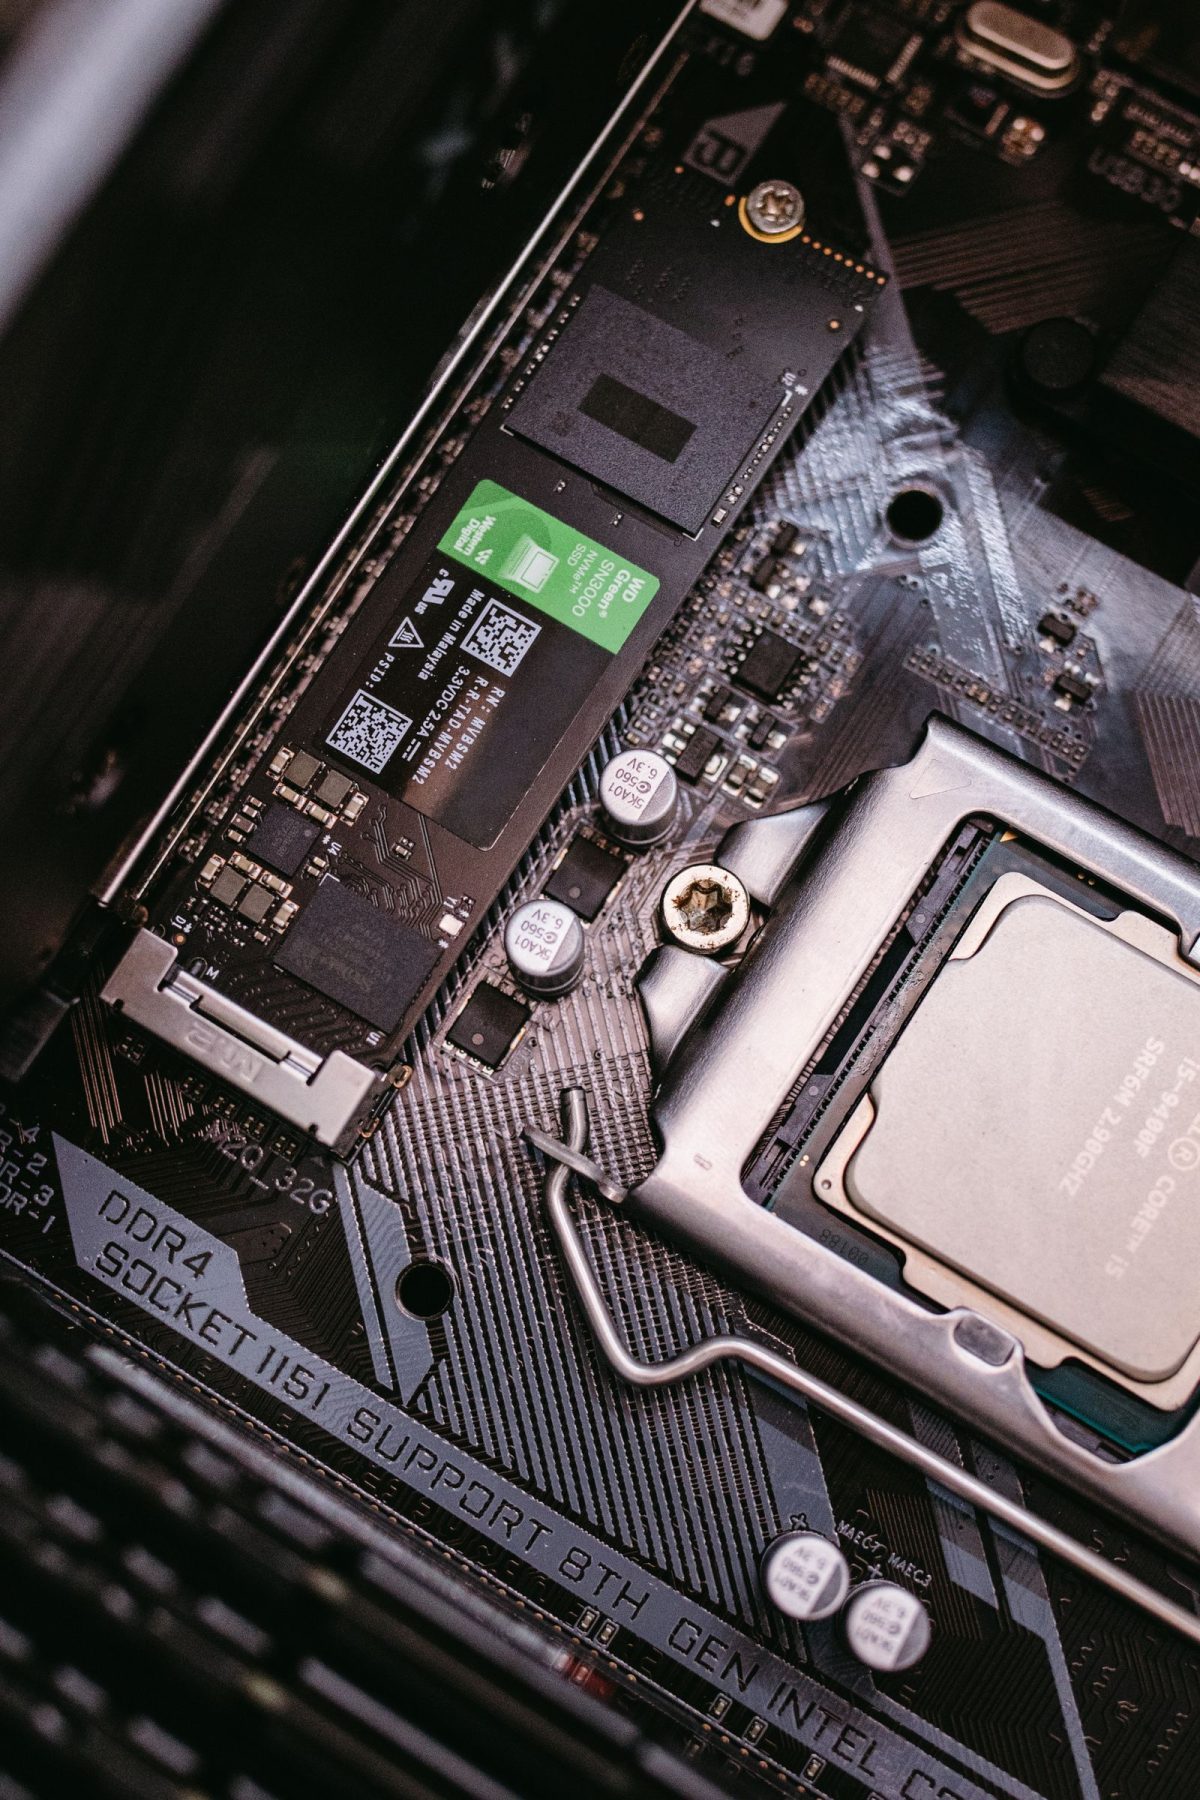
In NVMe Figure 207, Percentage Used is the manufacturer's estimate of consumed endurance. It can exceed 100; reaching 100 does not itself establish failure. Available Spare is remaining reserve capacity, evaluated against its separate threshold. It does not describe free space in your file system.
These percentages therefore point in different directions. Do not subtract an arbitrary application's health score from 100 unless its documentation says that score derives from Percentage Used. For SATA, the smartctl manual warns that attributes are vendor-specific, and labels may be wrong for an unrecognized SSD. A raw SATA number is not automatically a percentage.
Hypothetically, a report with Percentage Used at 18 and Available Spare at 100 does not contain a contradiction: the endurance estimate has advanced while the reserve indicator remains full. It also does not say the drive has exactly 82 percent of its calendar life remaining. Tomorrow's workload, the estimate's assumptions and failures unrelated to wear prevent that conclusion.
Use wear to plan a convenient migration window. A computer needed for tomorrow's event warrants a different replacement schedule from a spare machine holding reproducible downloads. That scheduling judgment comes from the cost of interruption, not from an imaginary countdown hidden in the report.
Give active warnings priority over reassuring wear
Microsoft's NVMe health-log reference describes Critical Warning as current state, with separate bits for conditions including insufficient spare capacity, temperature thresholds, degraded reliability and read-only media. Multiple conditions can coexist. A zero value means those warnings are absent at capture time; it does not certify every file.
Read the decoded condition rather than treating a nonzero hexadecimal value as a severity score. If your utility leaves it undecoded, retain the exact value and ask the drive maker's support team to interpret it against the applicable specification.
| Condition | Practical next step |
|---|---|
| Degraded reliability or read-only media | Prioritize rescue and arrange replacement; low estimated wear does not cancel the warning. |
| Spare below its reported threshold | Verify the backup and arrange migration promptly. |
| Temperature warning | Pause unnecessary heavy activity, check normal airflow, and capture again after cooling. |
| No active warning | Continue reading the error history and checking symptoms before deciding to keep using it. |
These are decision rules, not manufacturer warranty criteria. If cooling clears a temperature warning, record both reports and the conditions. Repeated warnings during ordinary work still need investigation. Do not invent a universal safe temperature or dismantle a laptop merely to improve a number.
Turn a lifetime counter into a dated observation
The health-log definitions distinguish unrecovered media/data-integrity errors, lifetime error-log entries, and unsafe shutdowns. Those are different events. An unsafe-shutdown count records loss of power without the expected shutdown notification; it is not a count of ruined files. A total error-log count alone does not explain its entries.
Write a small comparison record: capture date, drive identity, Percentage Used, spare and threshold, warning value, media-error count, and the symptom that prompted the check. If the drive is stable and files are protected, capture again after a week of ordinary use. That week is a suggested observation interval, not a validated prediction method. New symptoms or active warnings override the schedule.
A hypothetical media-error count of three that remains three has a different evidential meaning from three becoming nine alongside failed reads. Neither report identifies which personal files were affected. Preserve the detailed log for support rather than assuming the total names a failed component. A clean report also cannot explain away a repeatable application read error.
Keep units attached to numbers. A displayed total in terabytes and an underlying device counter may use different scaling; compare like with like rather than deriving a wear rate from mismatched fields.
Two hypothetical reports, two sensible replacement decisions
Report A: Percentage Used is 103, spare remains above its threshold, Critical Warning is zero, no new media errors appear, and ordinary reads succeed. This supports planning replacement because estimated endurance is consumed. It does not establish that the drive has already failed. Verify a restore, schedule migration, and avoid keeping irreplaceable material solely on it while waiting.
Report B: Percentage Used is 4, but the controller reports degraded reliability and files intermittently fail to read. This supports immediate data-preservation work and replacement planning despite the attractive wear estimate. Running a benchmark to prove the drive is still fast would not resolve the relevant question.
Before retiring either drive, restore several important files from the independent backup to a separate location and open them in their applications. Follow the backup verification guide for a fuller check. After migration, verify essential documents and the applications you rely on before erasing or surrendering the old SSD. A successful boot alone does not establish a complete transfer.
If you cannot obtain trustworthy health data, the honest result is unknown. Keep the symptom record, confirm backup recovery, and seek model-specific support. Replacement can be a reasonable continuity choice under uncertainty; it should not require pretending an incomplete report predicted the future.
Sources, versions & scope
The steps describe the documented controls and expected checks; they are not a claim that every device or software release has been physically tested. Platform and version differences are stated with the procedure.